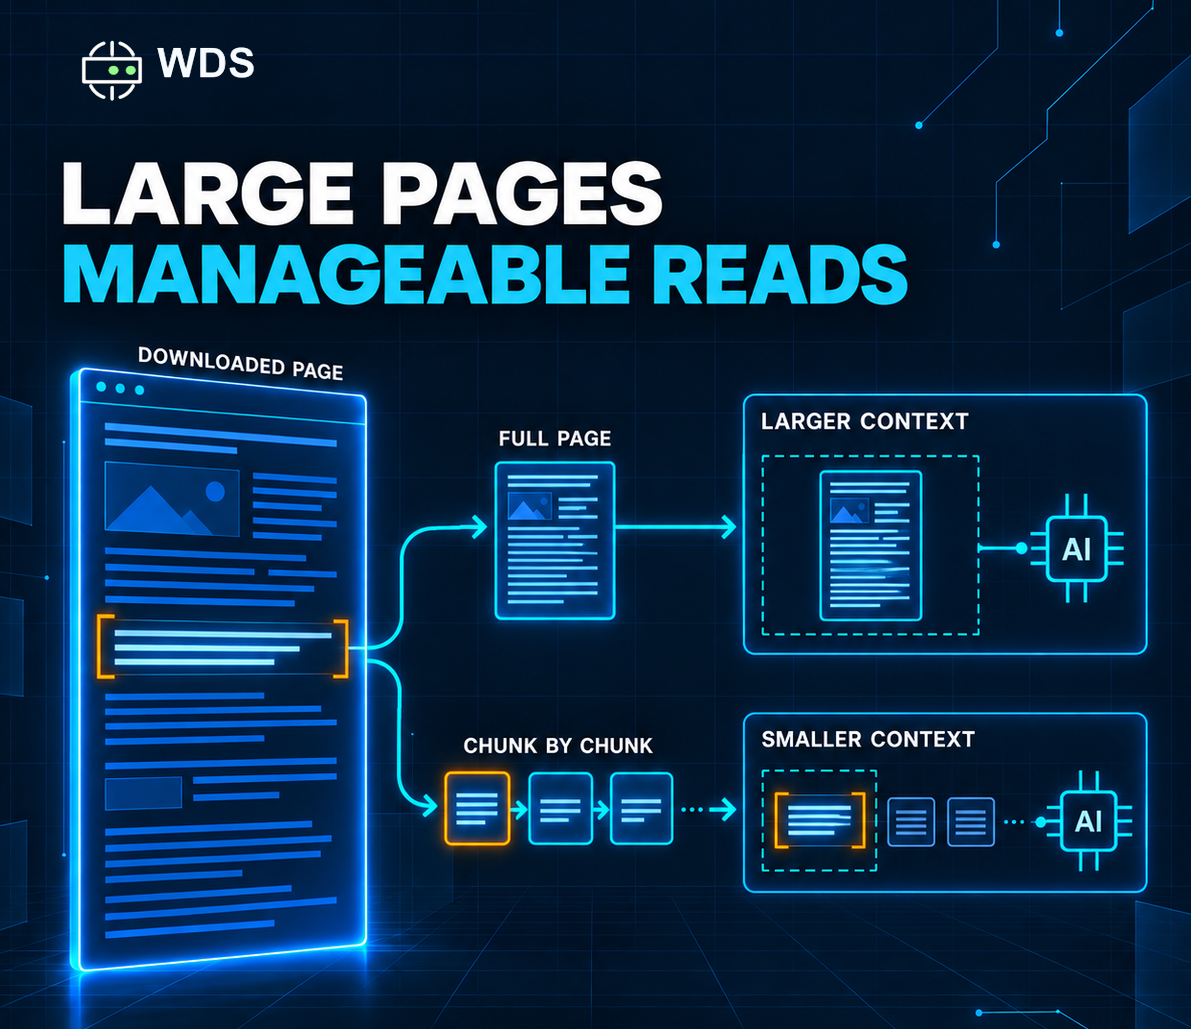
Let your AI agent read progressively through large pages.
Read large pages in manageable portions with WDS MCP tools while managing your AI model’s available context.
Latest how-tos, release notes, and product updates from the WDS team.
Read large pages in manageable portions with WDS MCP tools while managing your AI model’s available context.
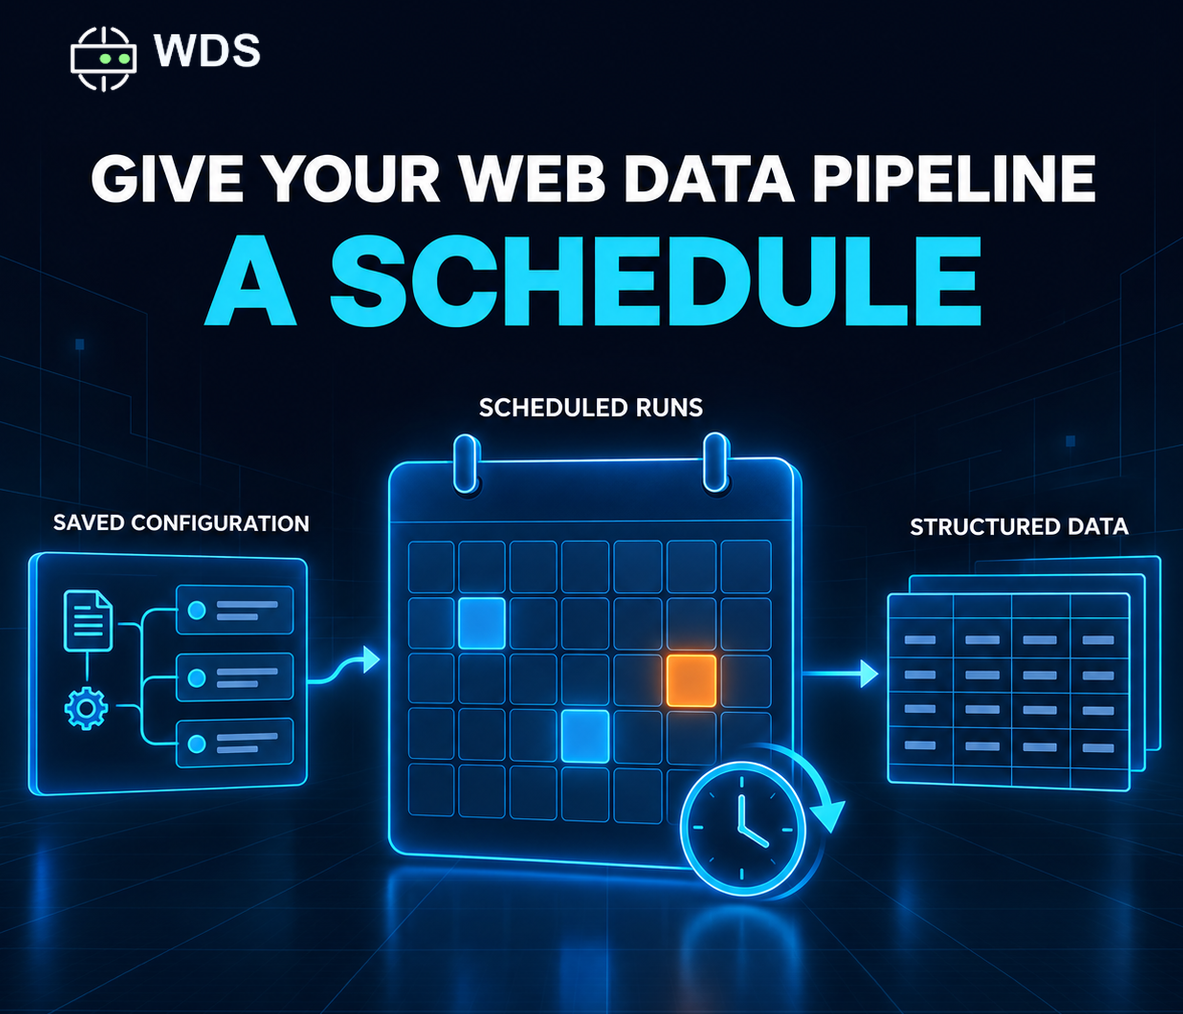
Turn a saved WDS crawling and extraction configuration into recurring collection with Traversal Scheduling.
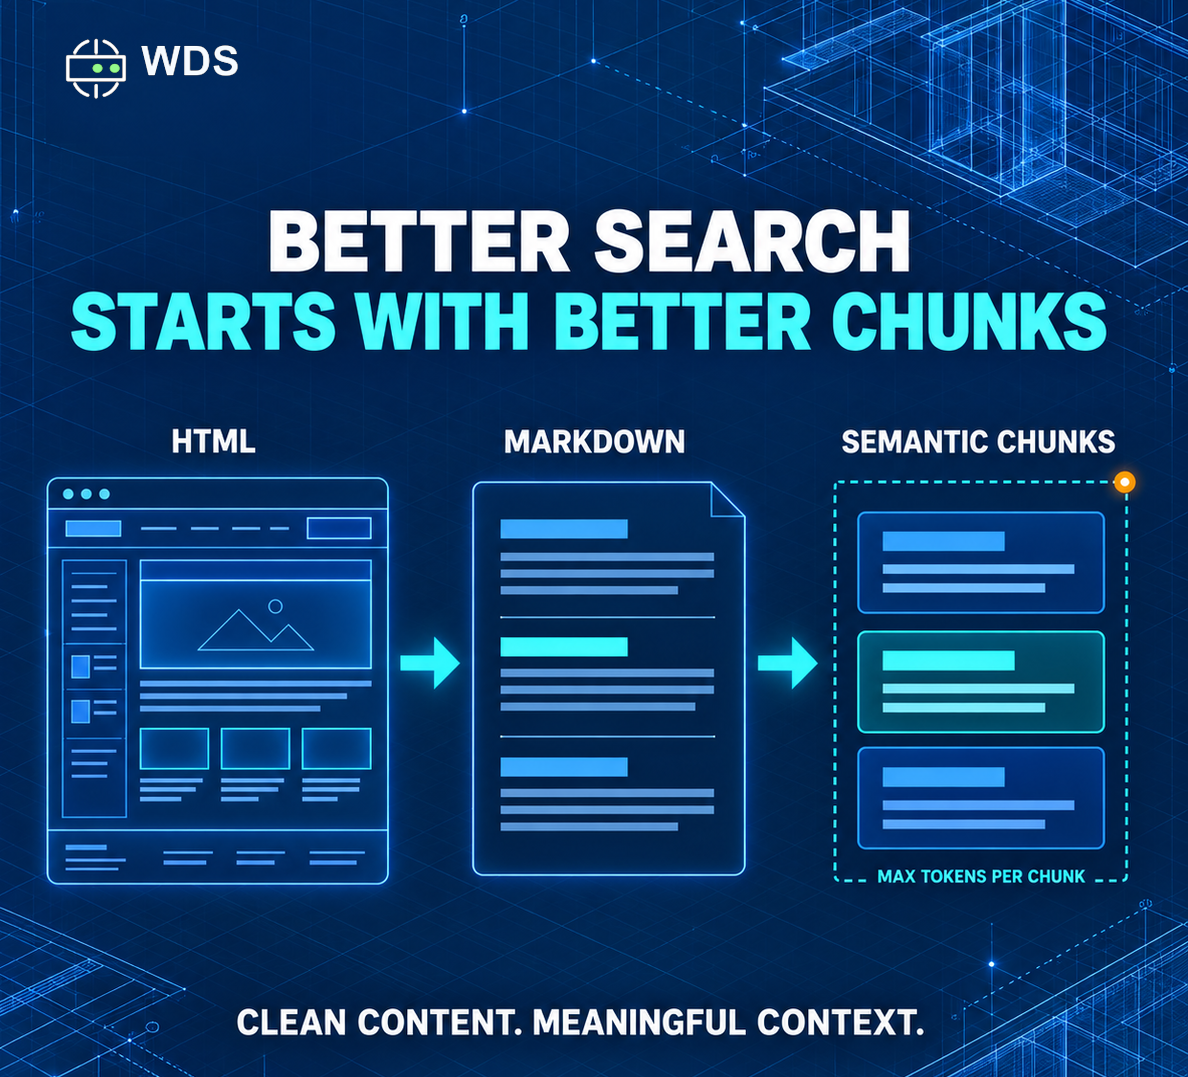
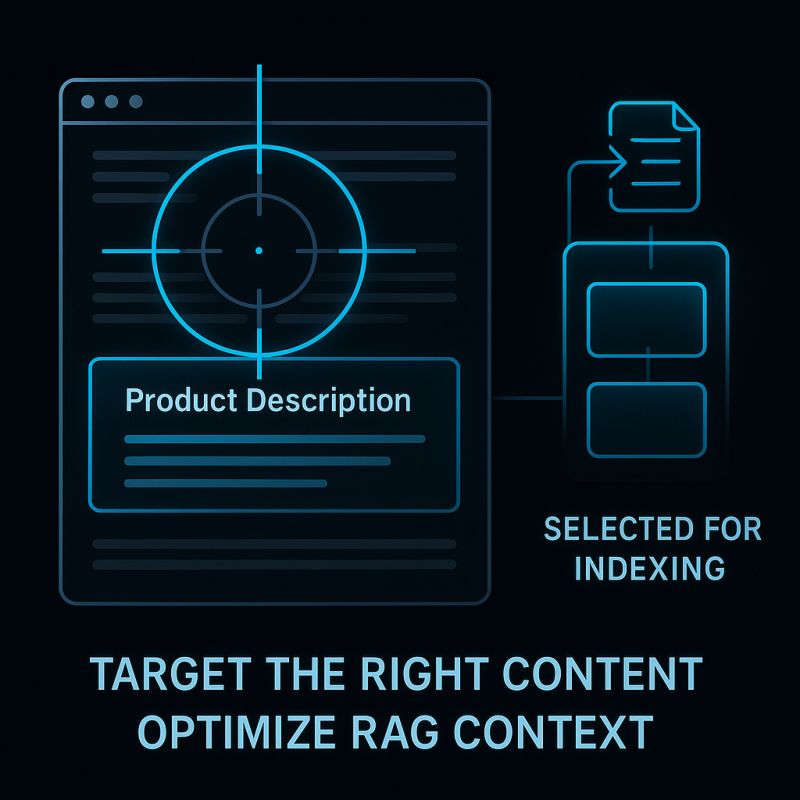
WDS converts HTML into Markdown and semantic chunks to prepare cleaner, more coherent context for retrieval and downstream AI answers.
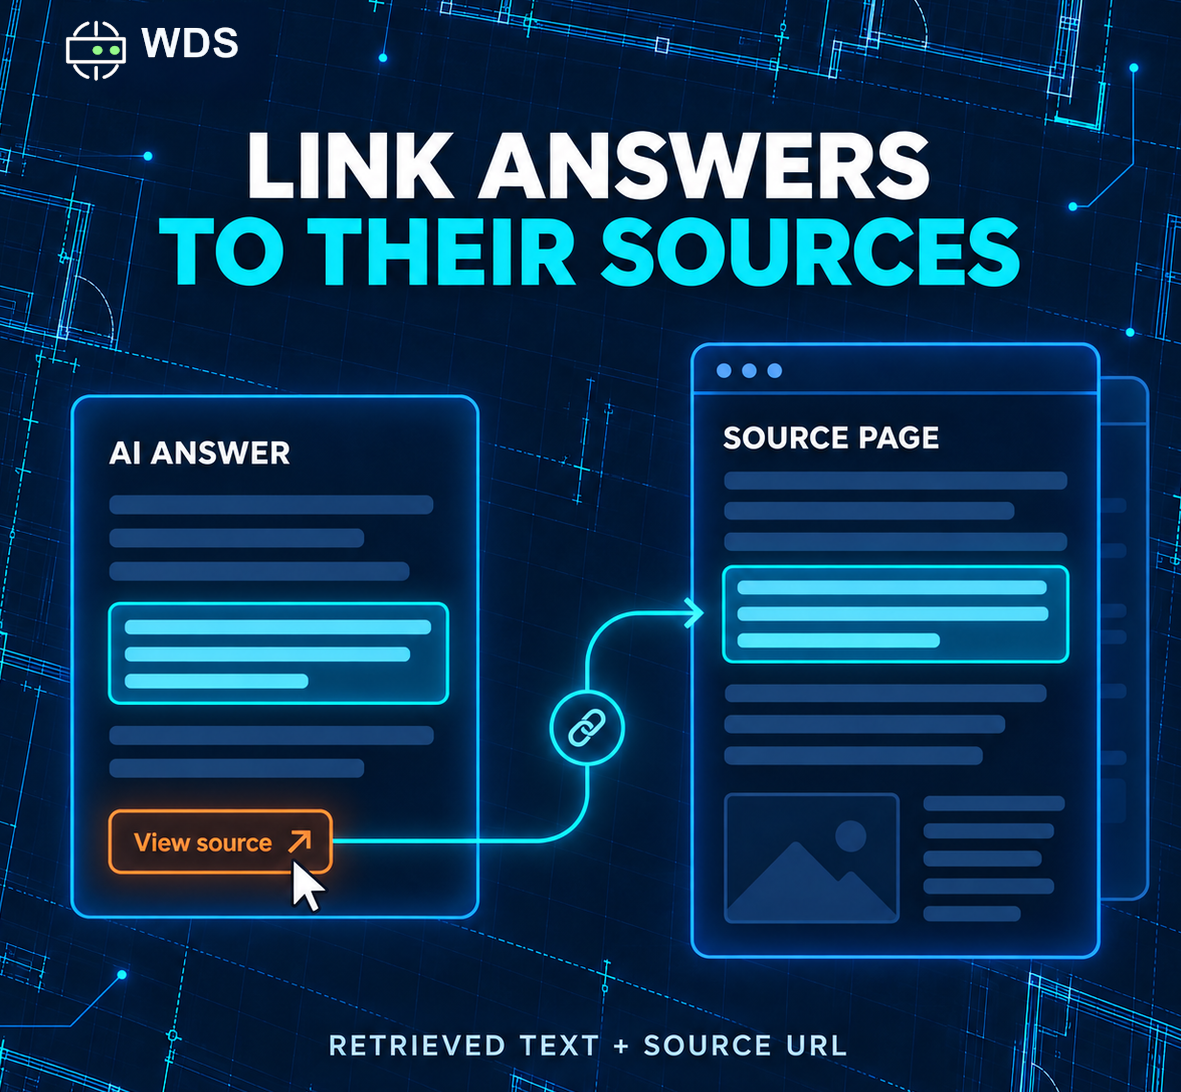
WDS returns matched text with source page URLs so your RAG application can connect answers to supporting evidence.
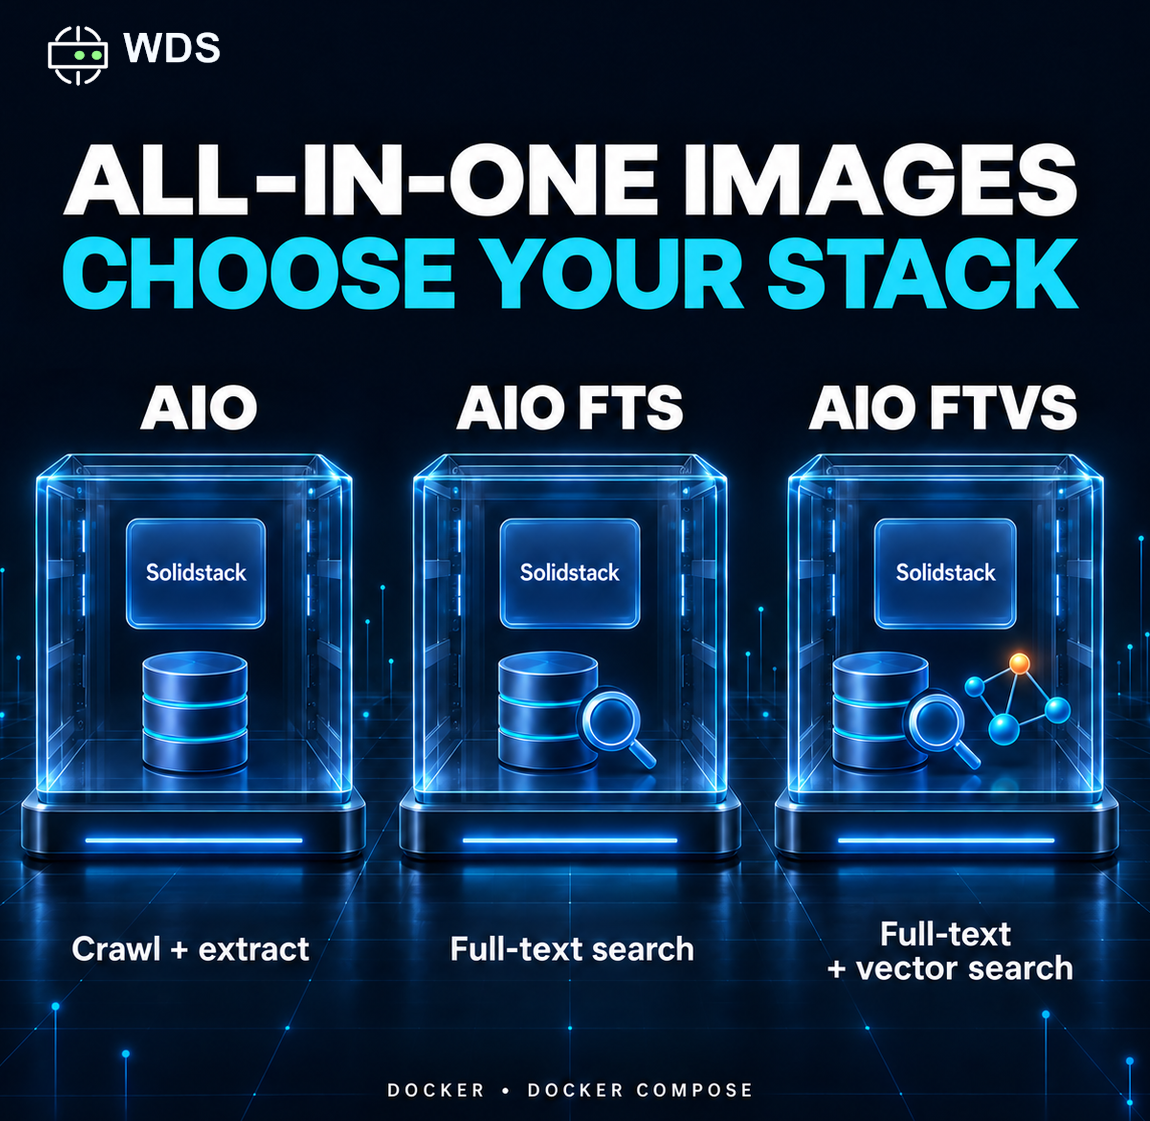
Solidstack All-in-one images reduce setup by packaging WDS and its supporting services in a single container for fast evaluation and small workloads.
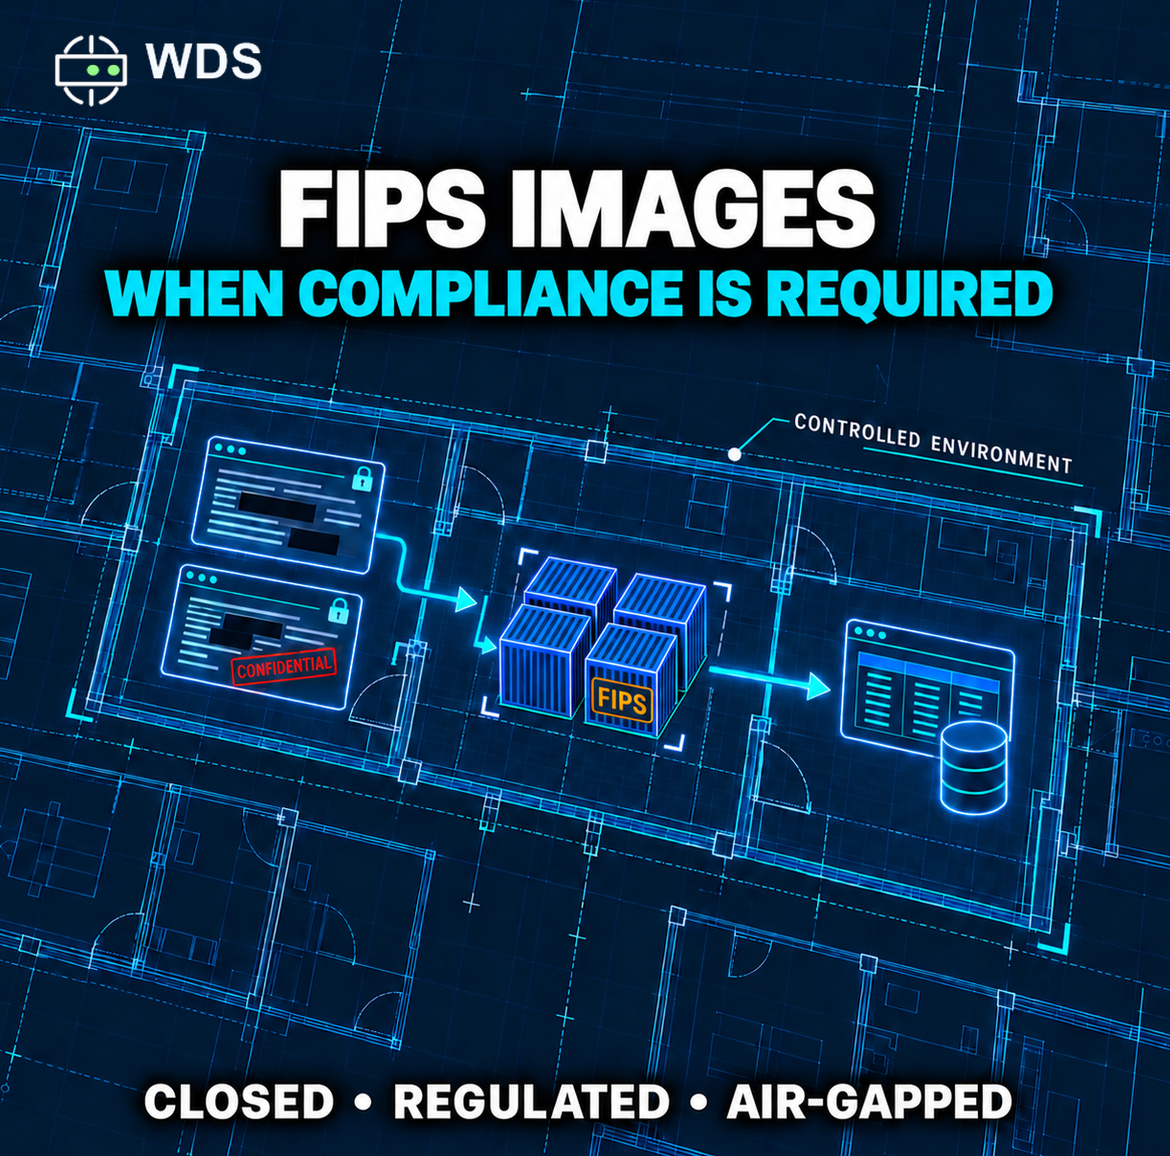
FIPS container image variants expand WDS deployment options for controlled environments, including air-gapped networks.
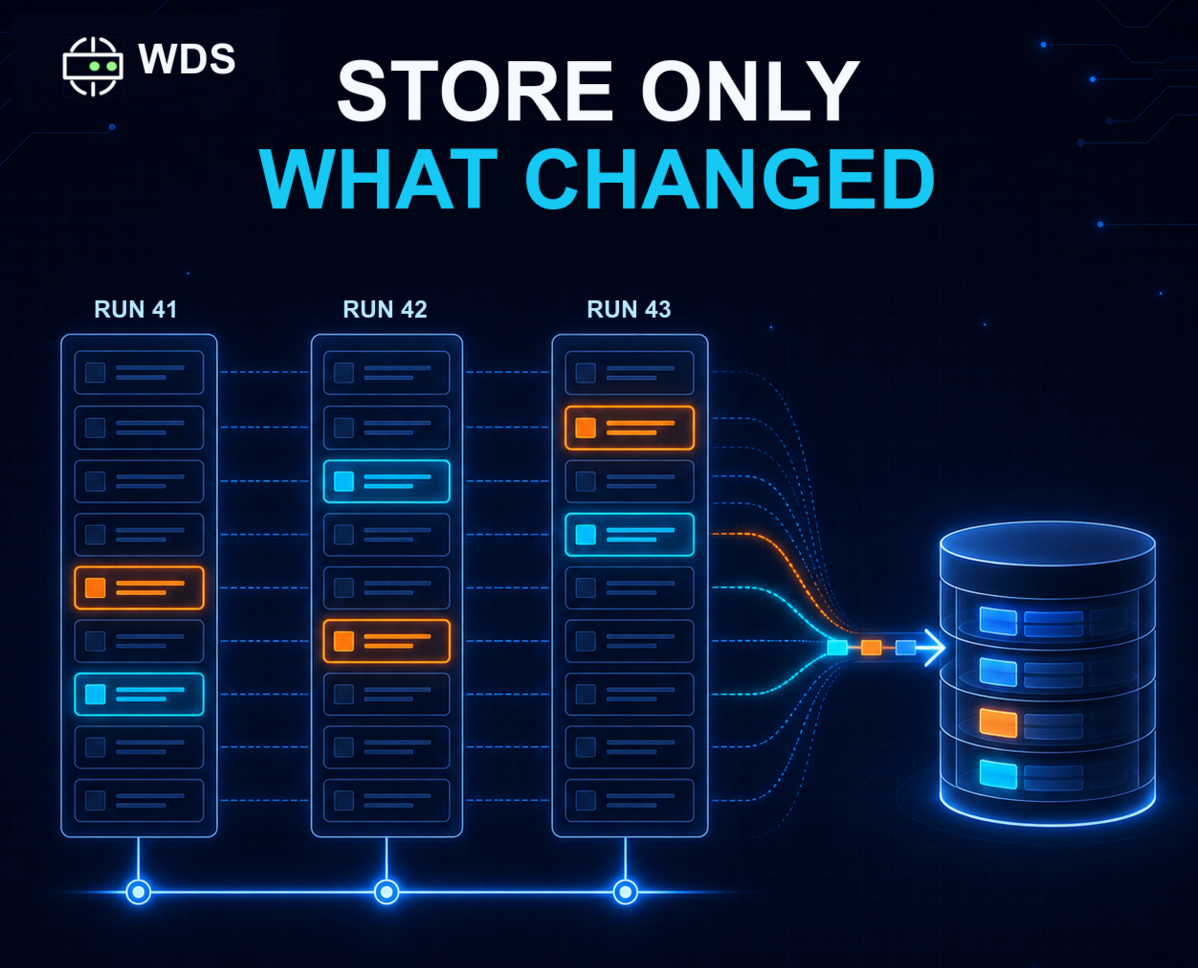
Keep recurring Traversal collection lean with incremental storage and complete run snapshots on read.
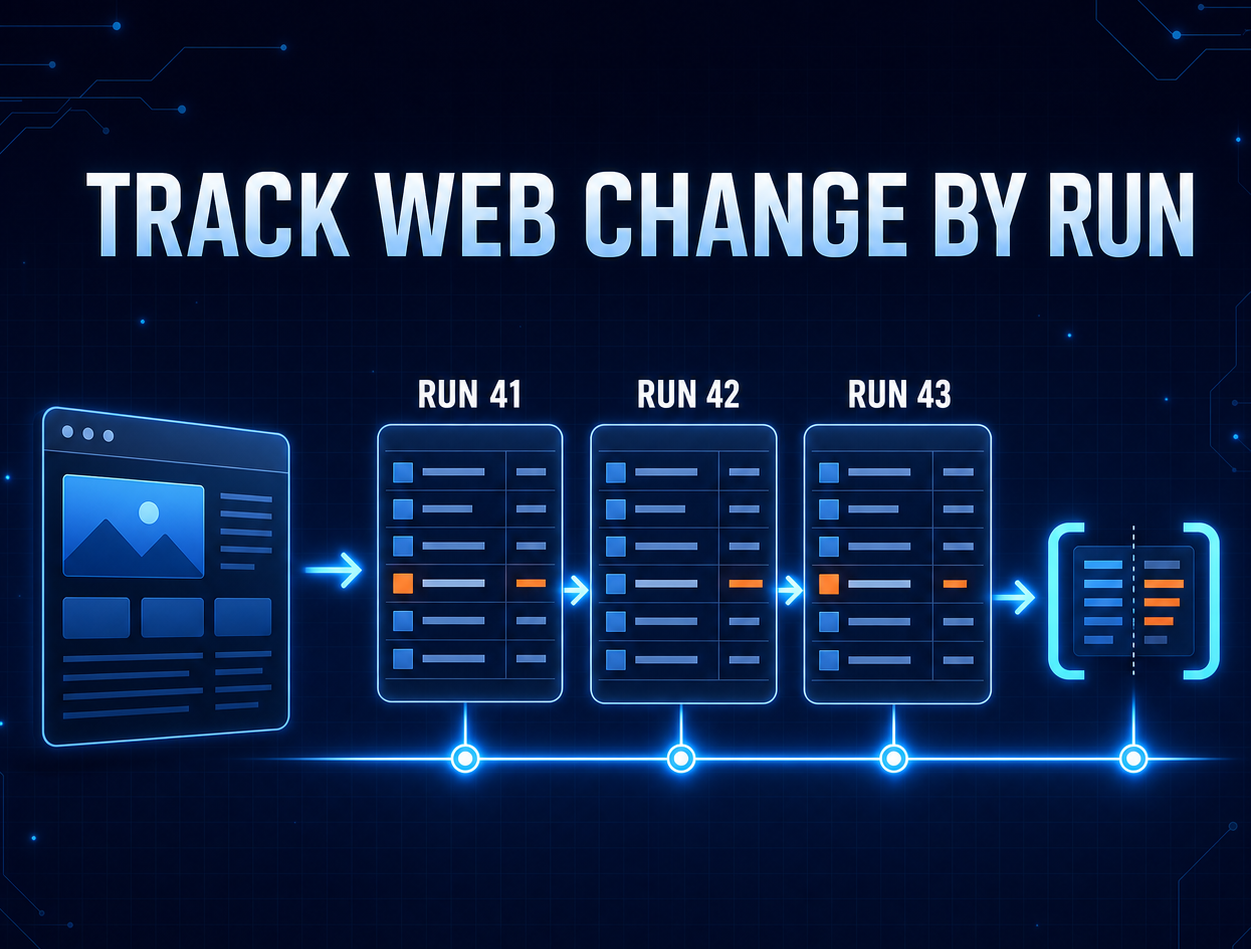
Compare WDS Traversal runs to see what changed across recurring web data collection.
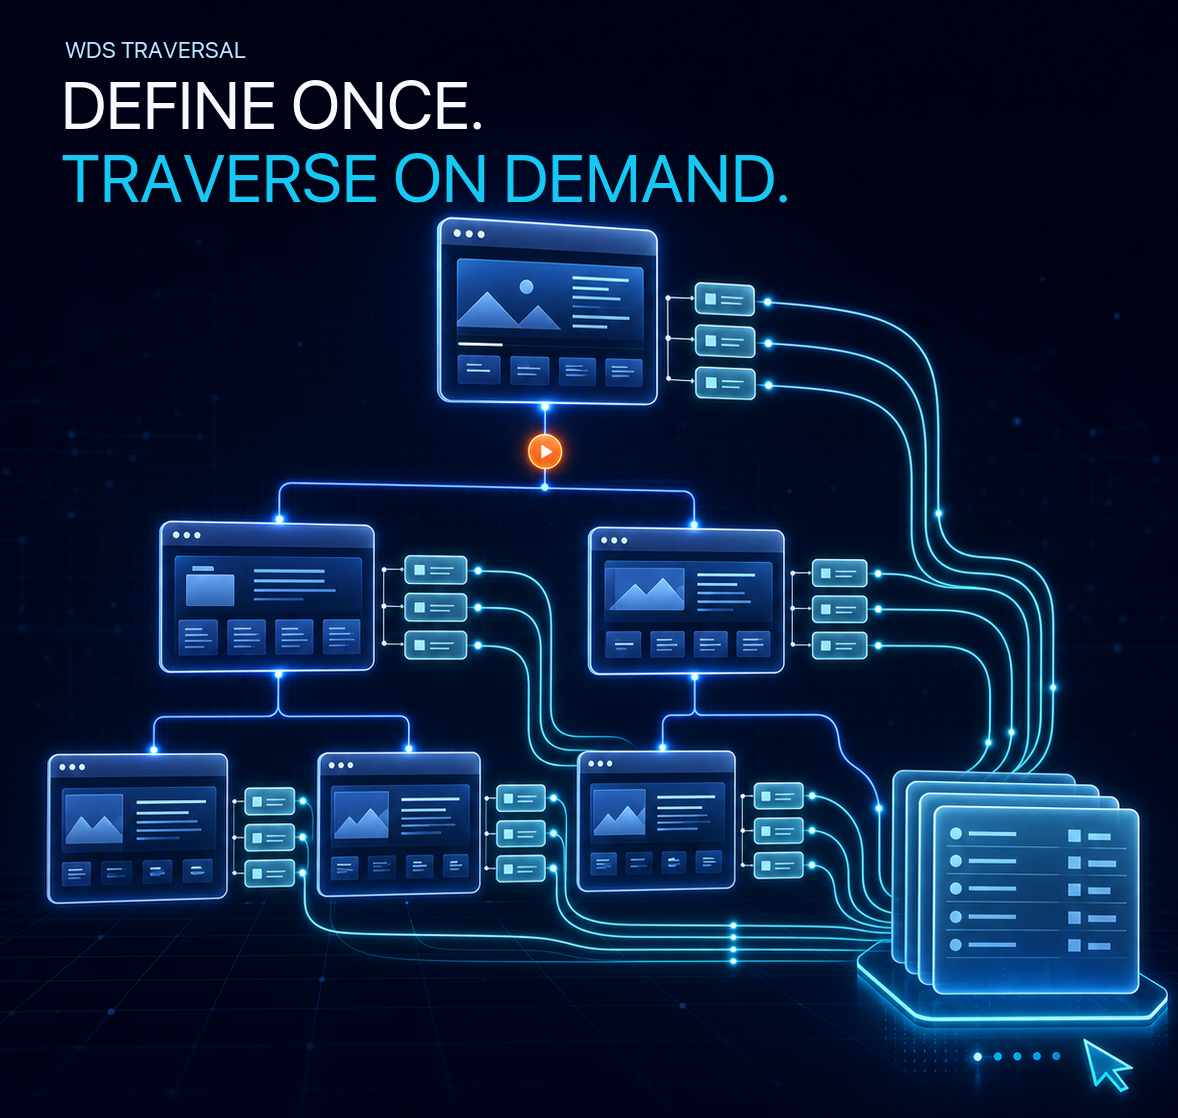
WDS Traversal turns website graphs into tree-shaped collection plans, with no configuration loops by design.
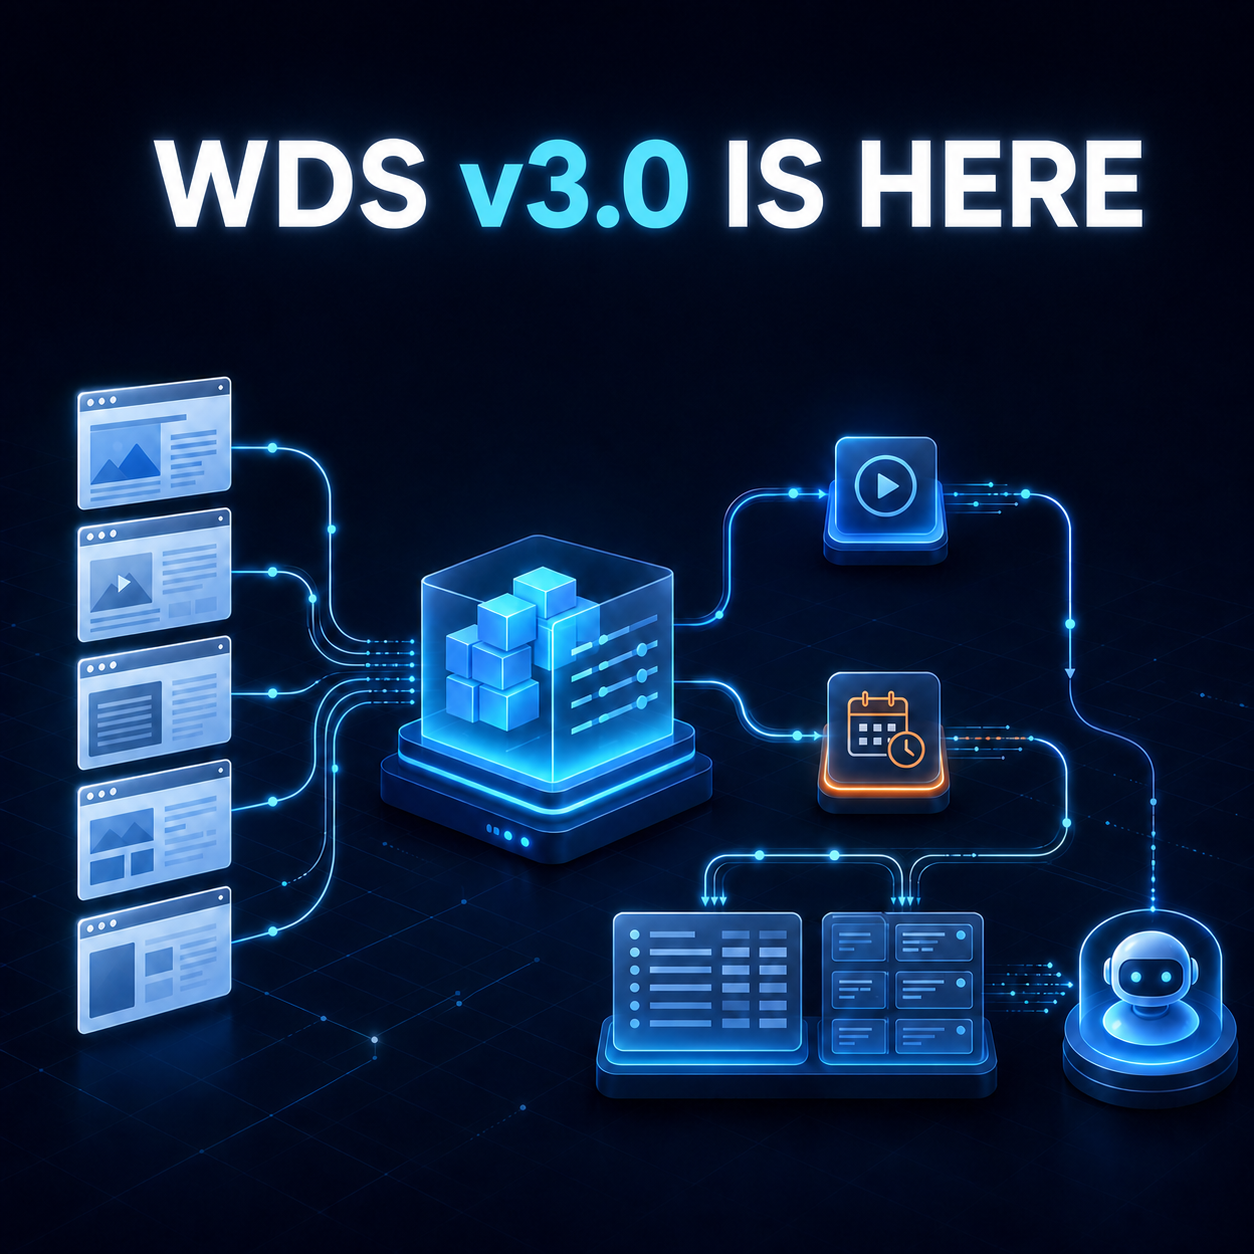
WDS v3.0 turns web crawling into a reusable, trackable workflow with on-demand runs, recurring schedules, and AI-ready results.
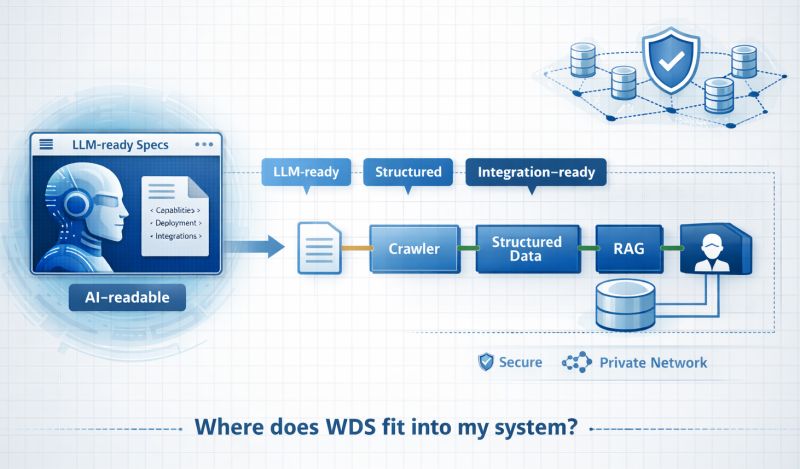
WDS provides LLM-friendly documentation that helps AI determine fit, integration points, and workflow coverage automatically.
Launch Web Data Source locally in minutes with the Docker Compose deployment path and start exploring crawling, extraction, and AI-ready workflows right away.
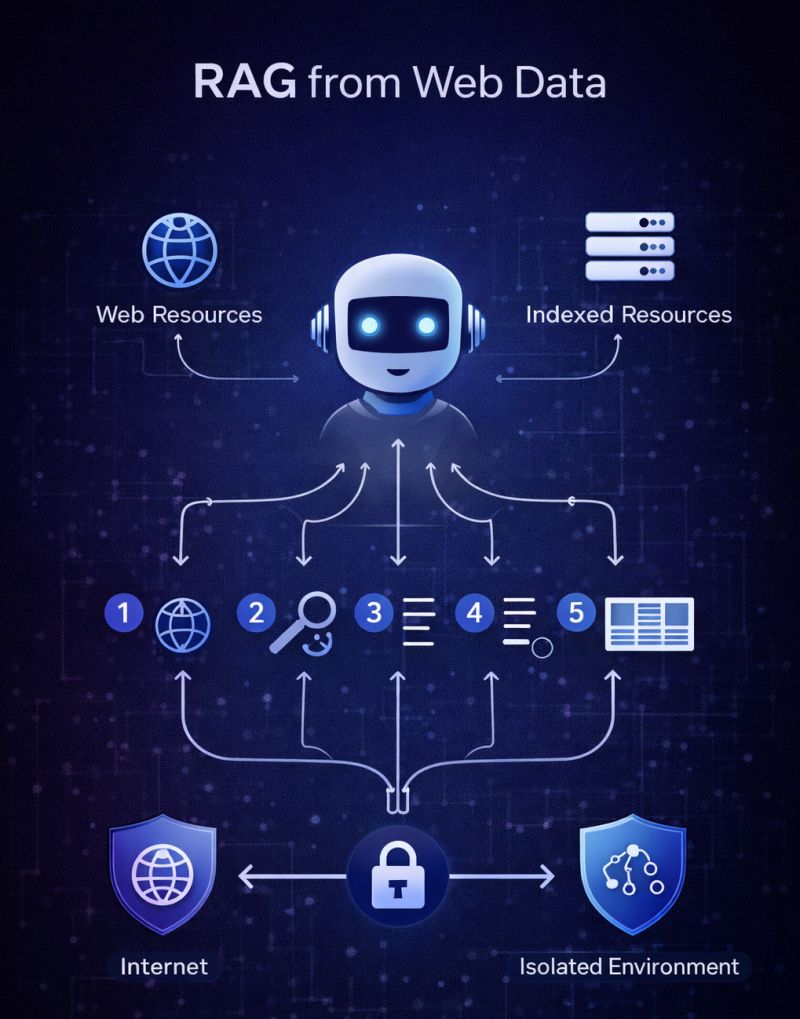
A transparent Retrieval-Augmented Generation workflow that lets AI agents query indexed web resources with explainable, verifiable retrieval.
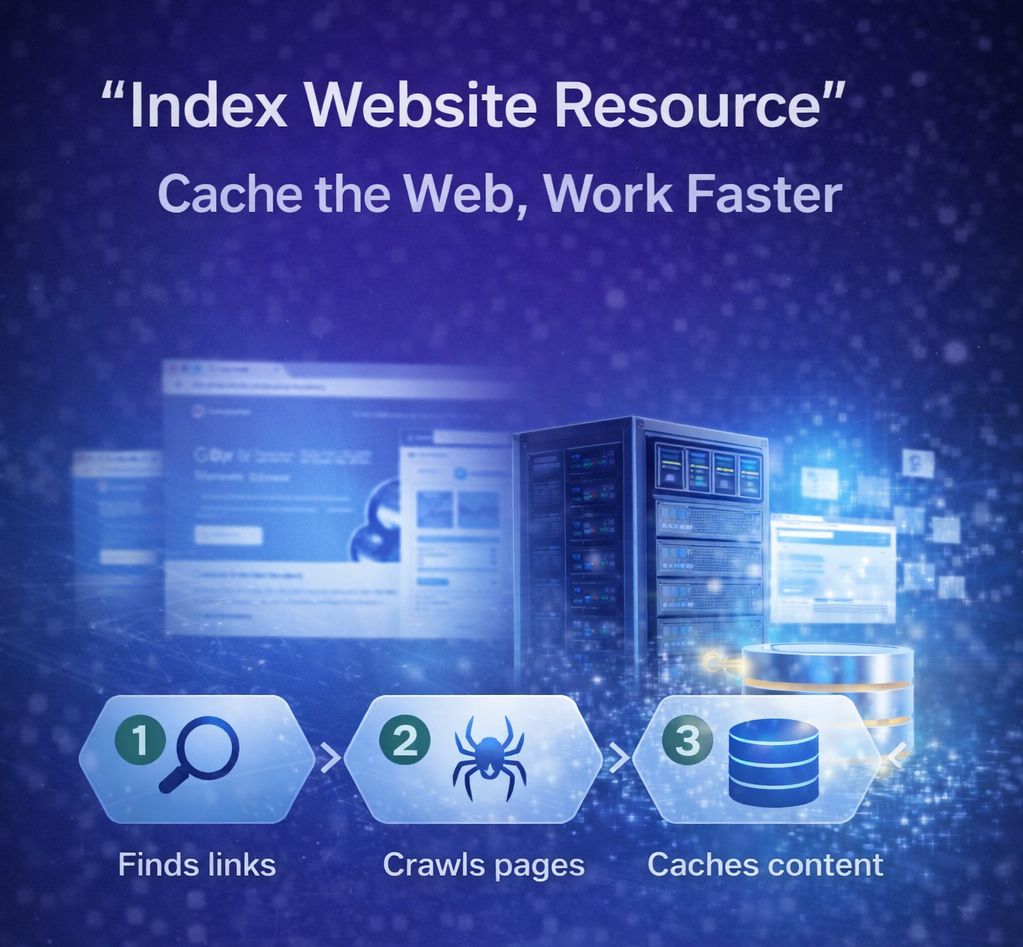
Preload entire websites into cache during off-hours so WDS workflows run on local, stable data instead of live pages.
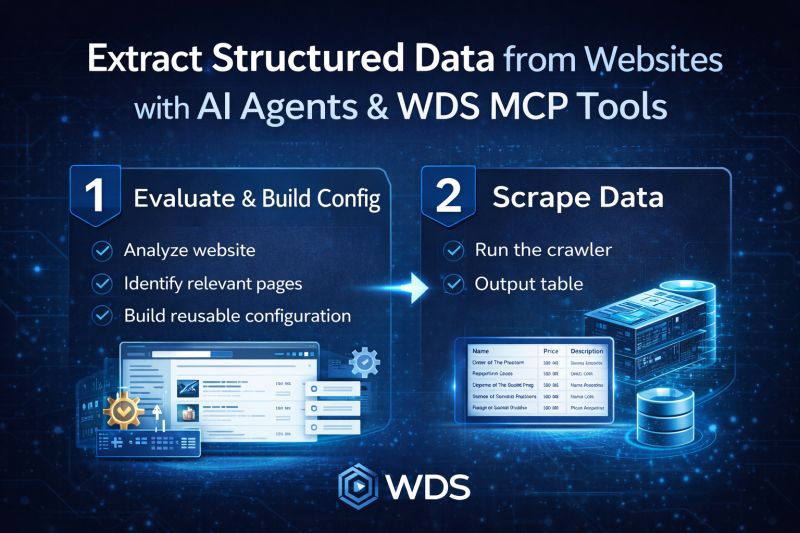
Structured website data extraction with AI agents and reusable WDS MCP crawling configurations.
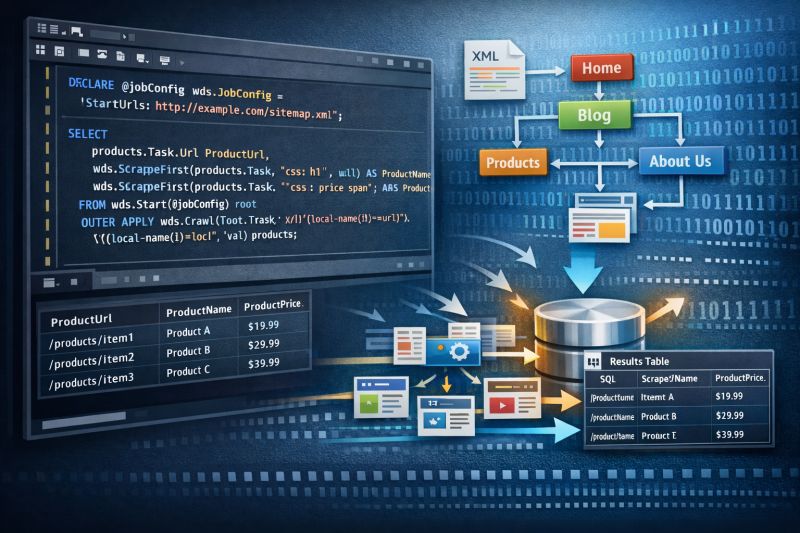
Use MS SQL and Web Data Source to turn sitemap-driven crawling into relational, queryable datasets.
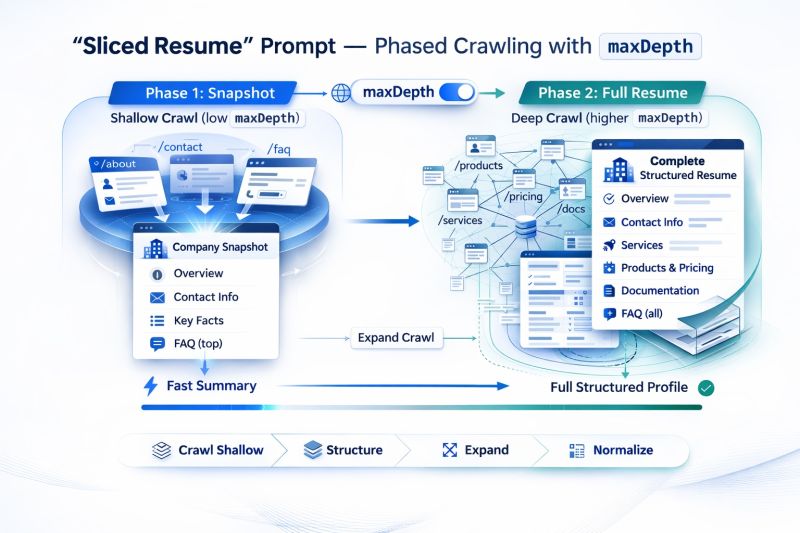
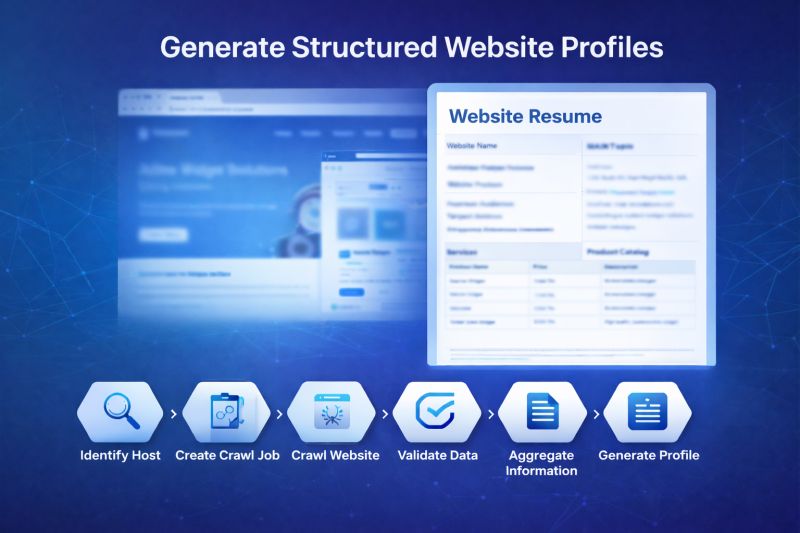
Progressive website profiling with phased crawling and structured expansion.
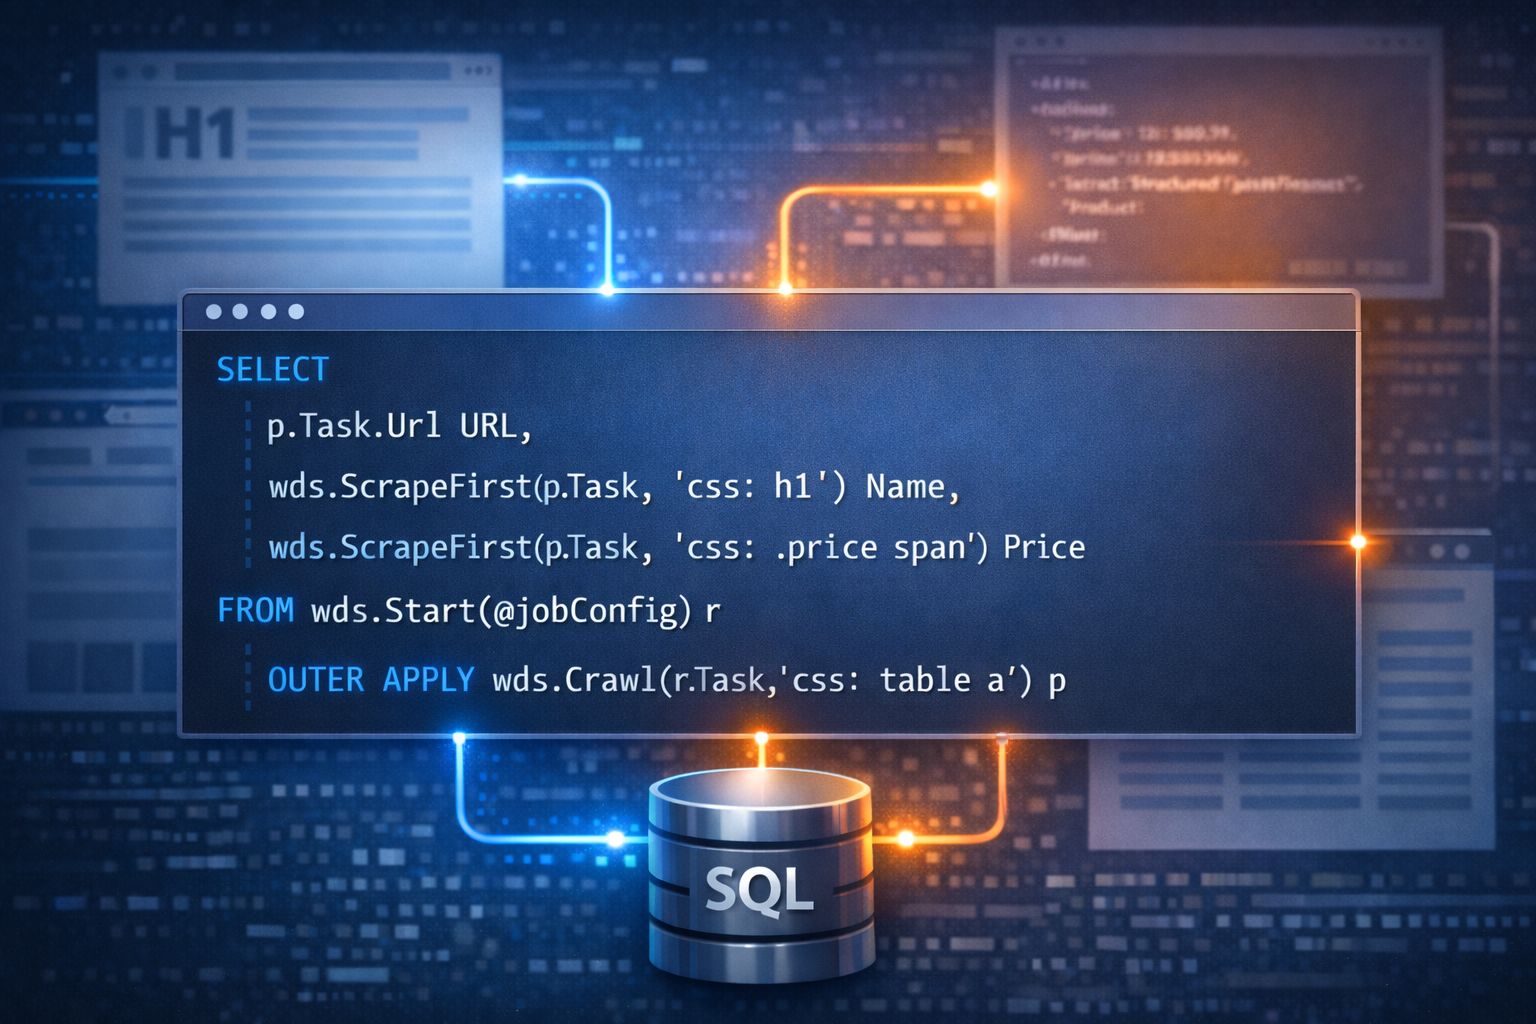
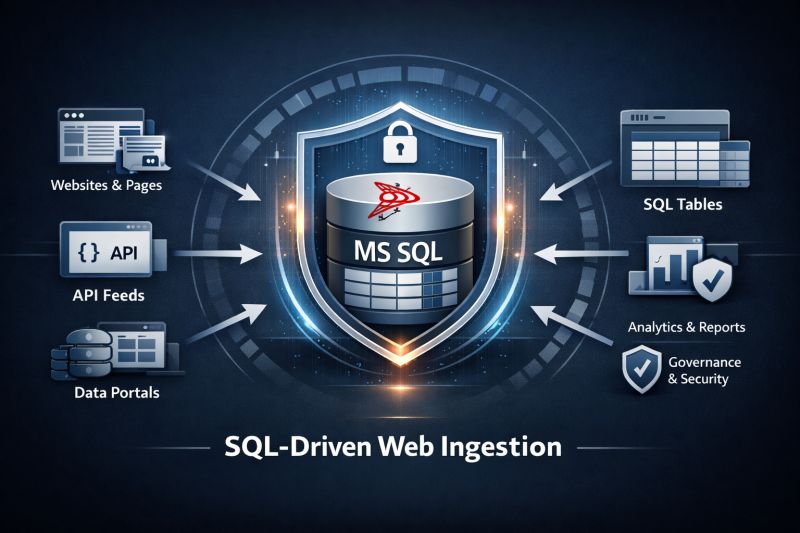
Web Data Source allows web resources to be queried and consumed directly from MS SQL.
Retrieval is not just a feature. It’s infrastructure for trustworthy RAG.